



Why Operational Failures Need Multiplayer AI
Why quality, maintenance and engineering problems need shared evidence, persistent context and multiplayer AI workflows rather than isolated copilots.
Roozbeh Bandpey
Gründer & CEOA recurring defect is almost never a quality problem alone.
The symptom may appear in a quality system. The evidence may sit in maintenance history. The contributing condition may be visible in production data. The design decision may live with engineering. The workaround may exist only in the head of an experienced technician.
Yet most enterprise software still asks each function to investigate its piece separately.
That is the gap Facthory is designed to close.
Facthory brings quality, maintenance, engineering, production evidence, expert knowledge, and AI agents into one persistent operational context. Instead of giving each team another isolated copilot, it gives people and specialist agents a shared place to investigate the same problem, in parallel, with the same evidence and the same history.
The core idea: operational failures are multiplayer problems. The AI system that investigates them should be multiplayer too.
Downtime is falling. The remaining problems are getting harder.
Manufacturers have made real progress on predictive maintenance. That does not mean the reliability problem is solved.
Siemens' True Cost of Downtime 2024 study found that a large plant now experiences an average of 25 unplanned downtime incidents per month, down from 42 in 2019. Monthly downtime fell from 39 hours to 27 hours. But average recovery time moved in the opposite direction, rising from 49 minutes to 81 minutes. Siemens attributes part of that increase to skills and knowledge gaps, supply-chain constraints, and the fact that easier failure modes are increasingly being caught earlier. The failures that remain are harder to diagnose and recover from. Source: Siemens, The True Cost of Downtime 2024
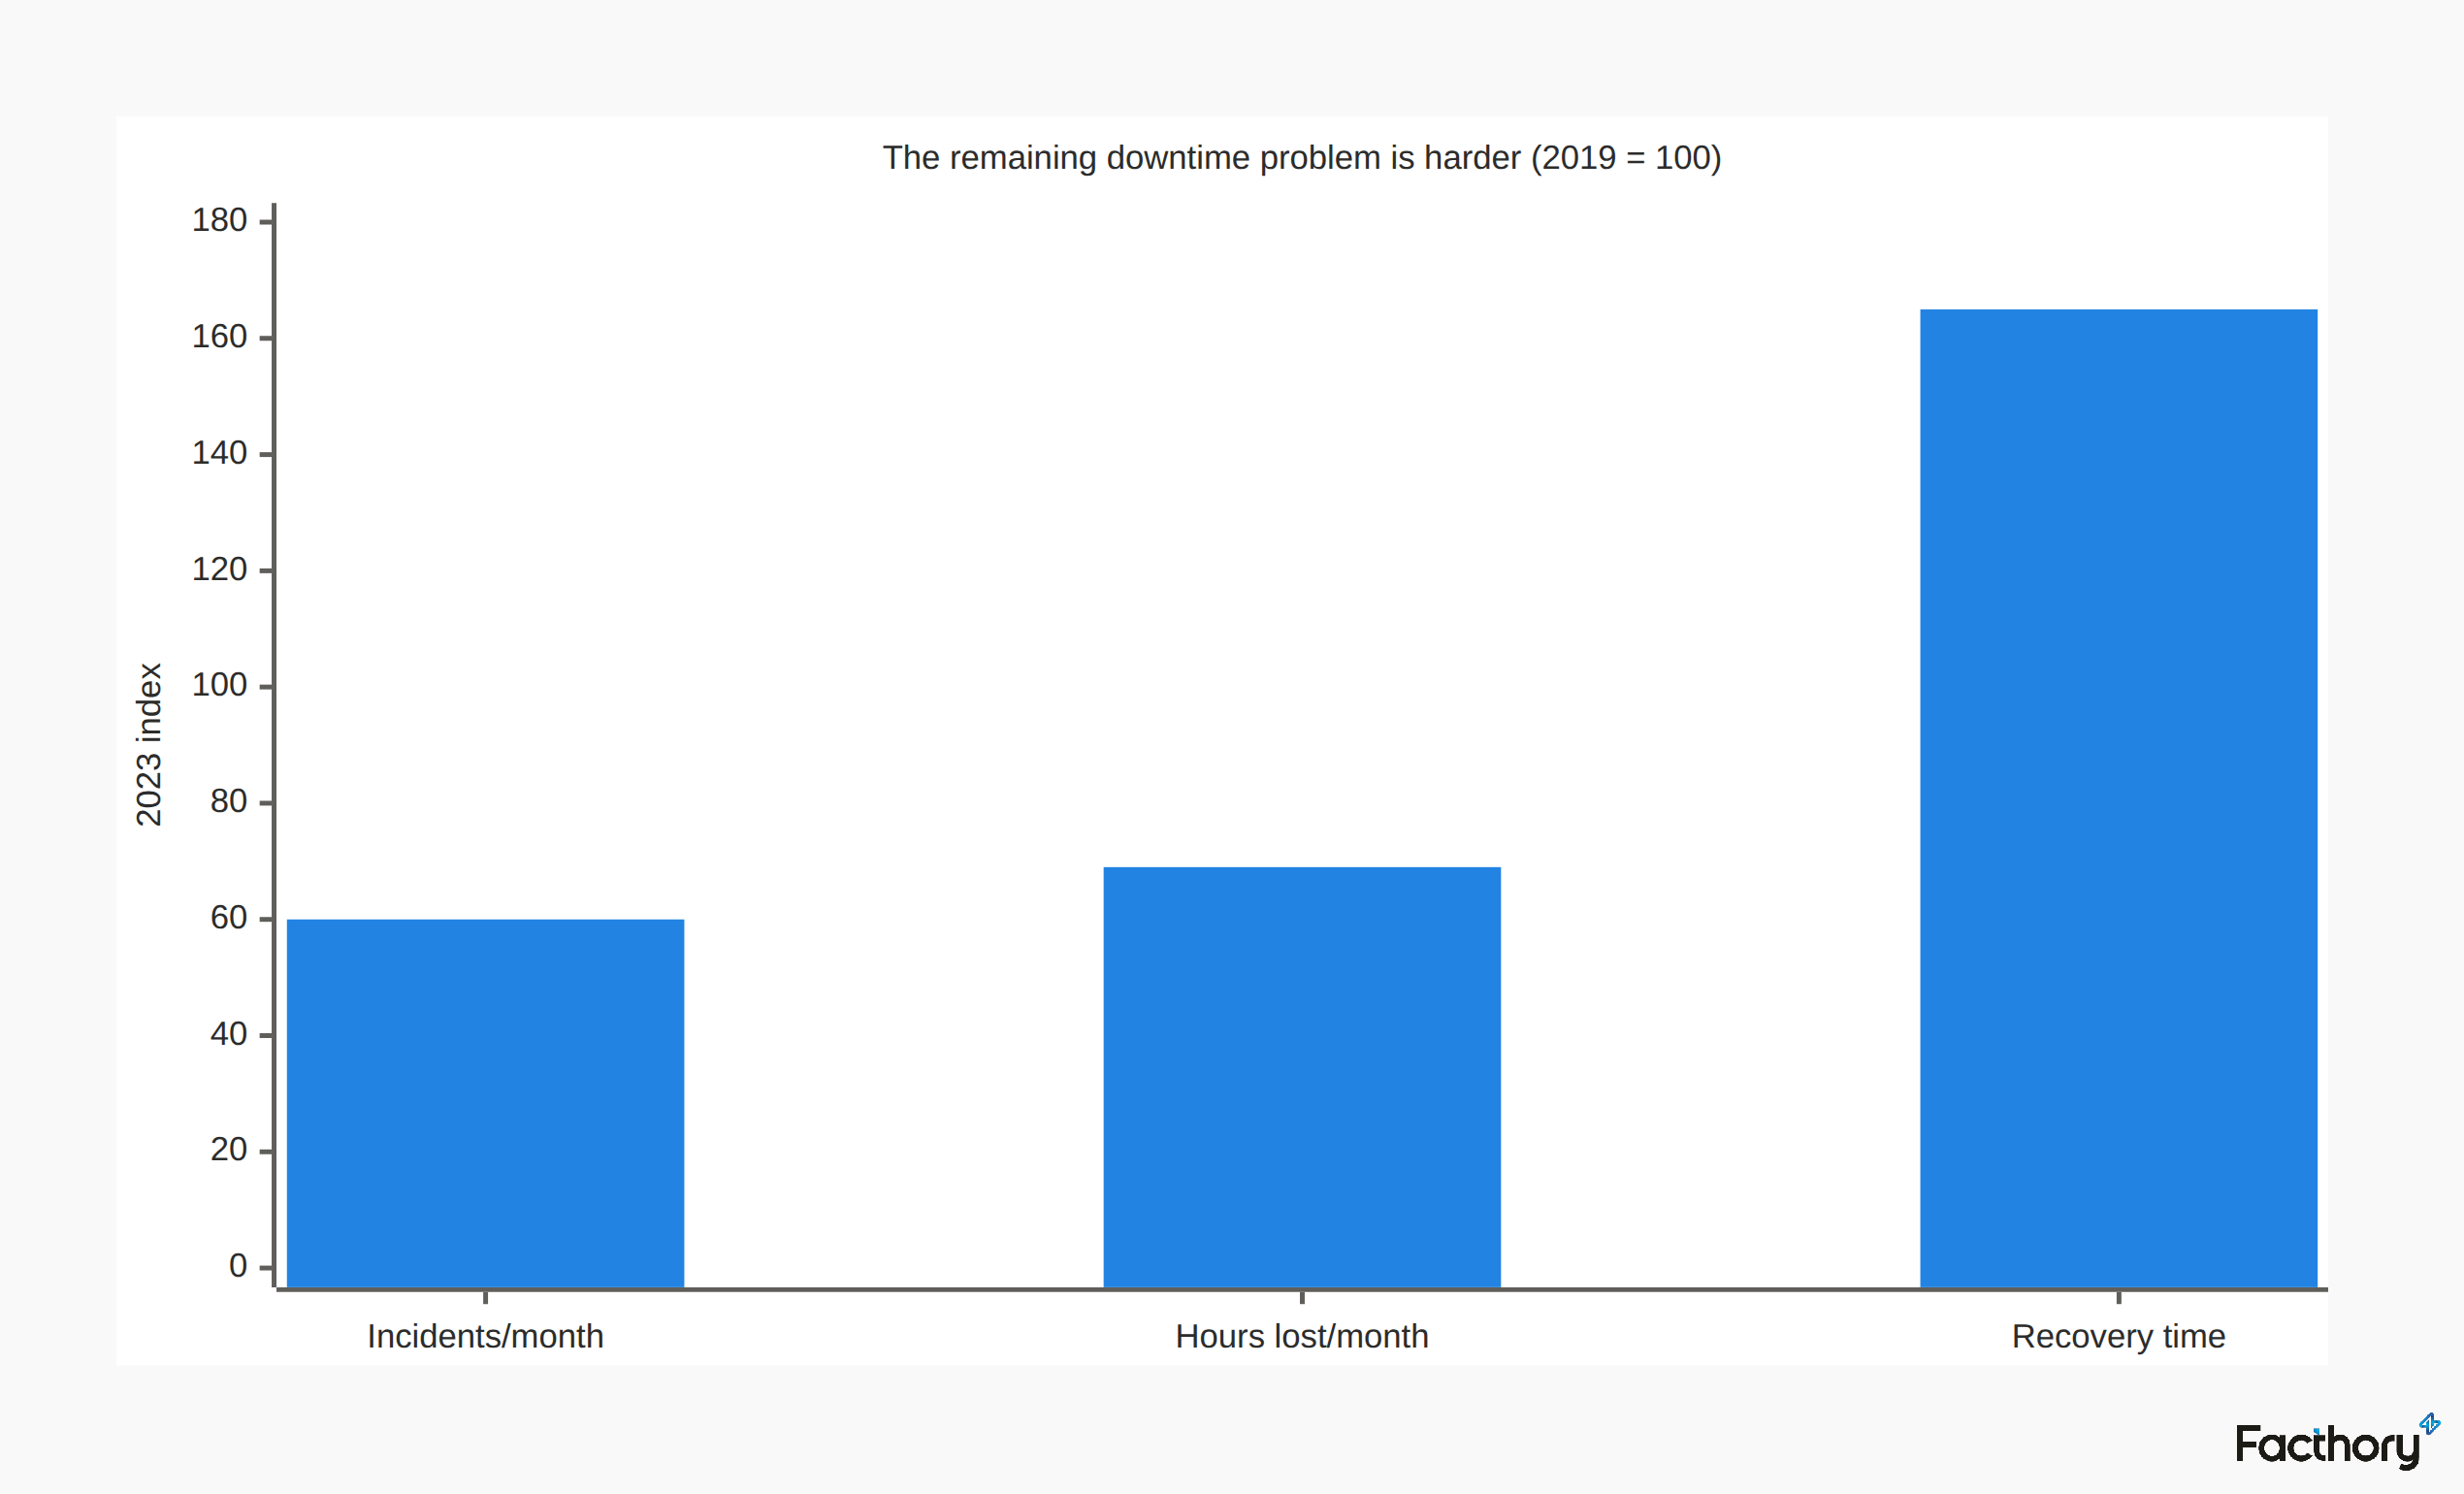
Chart methodology: 2019 is normalized to 100. Siemens reports 42 to 25 incidents per month, 39 to 27 downtime hours per month, and 49 to 81 minutes average recovery time. Rounded indices are 60, 69, and 165.
The implication is important. The next generation of operational improvement is not only about detecting that a machine is unhealthy. It is about resolving difficult failures faster by connecting the technical, historical, procedural, and human evidence around them.
That is inherently cross-functional.
A copilot in every silo is still a silo
The default enterprise AI pattern is single-player: one employee opens one assistant, asks a question, receives an answer, and closes the session.
That is useful for individual productivity. It is a poor operating model for a recurring production failure.
A real investigation may require a quality engineer to classify the defect, a reliability engineer to compare failure history, maintenance to inspect previous interventions, process engineering to test operating conditions, a supplier engineer to review incoming material, and a production lead to decide what can safely continue running.
Putting a separate AI assistant next to each person does not create a shared investigation. It creates several faster investigations that still have to be reconciled manually.
Facthory takes a different approach: multiplayer agentic work.
People and agents work inside the same persistent problem space. A reliability agent can analyze historical failures while a quality agent compares defect patterns. An engineering agent can inspect procedures, specifications, and technical evidence. Human experts can add context, reject a weak hypothesis, request another analysis, or approve a corrective action without reconstructing the case from scratch.
The work remains available after the meeting, shift, or chat ends.
| Single-player copilot | Facthory multiplayer workflow | |
|---|---|---|
| Working context | Individual session | Shared persistent investigation |
| Participants | One user and one assistant | Multiple people and specialist agents |
| Evidence | Reassembled per conversation | Shared across the investigation |
| Handoffs | Copy, summarize, forward | Continue from the same state |
| Outcome | Answer or draft | Investigation, decision, action, and reusable learning |
Quality improves when quality stops being somebody else's department
This is not only a software argument.
McKinsey found the same organizational pattern in manufacturing quality programs. In one industrial manufacturer, the underlying problem was that quality was treated as the responsibility of the quality organization rather than the wider operation. After quality became a cross-functional operating priority, customer complaints and quality-related costs both fell by more than 25%. In another example, end-to-end right-first-time production improved from 83% to more than 92%, while site productivity increased by more than 15%. Source: McKinsey, Manufacturing quality today
The same principle appears in maintenance. McKinsey reports that embedding digital collaboration into maintenance processes can reduce applicable maintenance spending by 10% to 15%, improve OEE by 2 to 3 percentage points, and increase wrench time by approximately 5% to 10%. Source: McKinsey, Digital collaboration for a connected manufacturing workforce
The pattern is consistent: better outcomes emerge when the people, evidence, and decisions around the problem stop being fragmented.
The data is already there. The context usually is not.
Most manufacturers are not starting from zero data.
Siemens reports that 87% of major manufacturers already gather data that can support predictive maintenance. Almost half have dedicated predictive-maintenance teams. Yet the same report notes that effective prediction depends on combining maintenance records, operational systems, MES data, service data, and human insight. Source: Siemens
That distinction matters.
A temperature signal can tell you that something changed. A maintenance record can tell you what was replaced. A quality record can tell you what defect appeared. An engineering specification can tell you the expected operating envelope. An experienced technician can tell you that the same vibration usually appears two shifts before the seal fails.
The value comes from reasoning across those signals together.
Facthory is built to connect that operational evidence into a Living Operational Model that people and agents can work from together. The objective is not another dashboard showing more disconnected indicators. It is a shared intelligence layer that preserves the relationship between the failure, the asset, the process, the evidence, the people involved, the corrective action, and what happened afterward.
The economic case is already visible
The upside of connected reliability intelligence is not theoretical.
Siemens reports the following results from clients using AI-driven predictive maintenance: 85% improvement in downtime forecasting accuracy, 50% reduction in unplanned machine downtime, 55% increase in maintenance staff productivity, and 40% reduction in maintenance costs. These are Siemens client results, not Facthory benchmarks, but they show the economic headroom available when machine data is converted into operational decisions. Source: Siemens
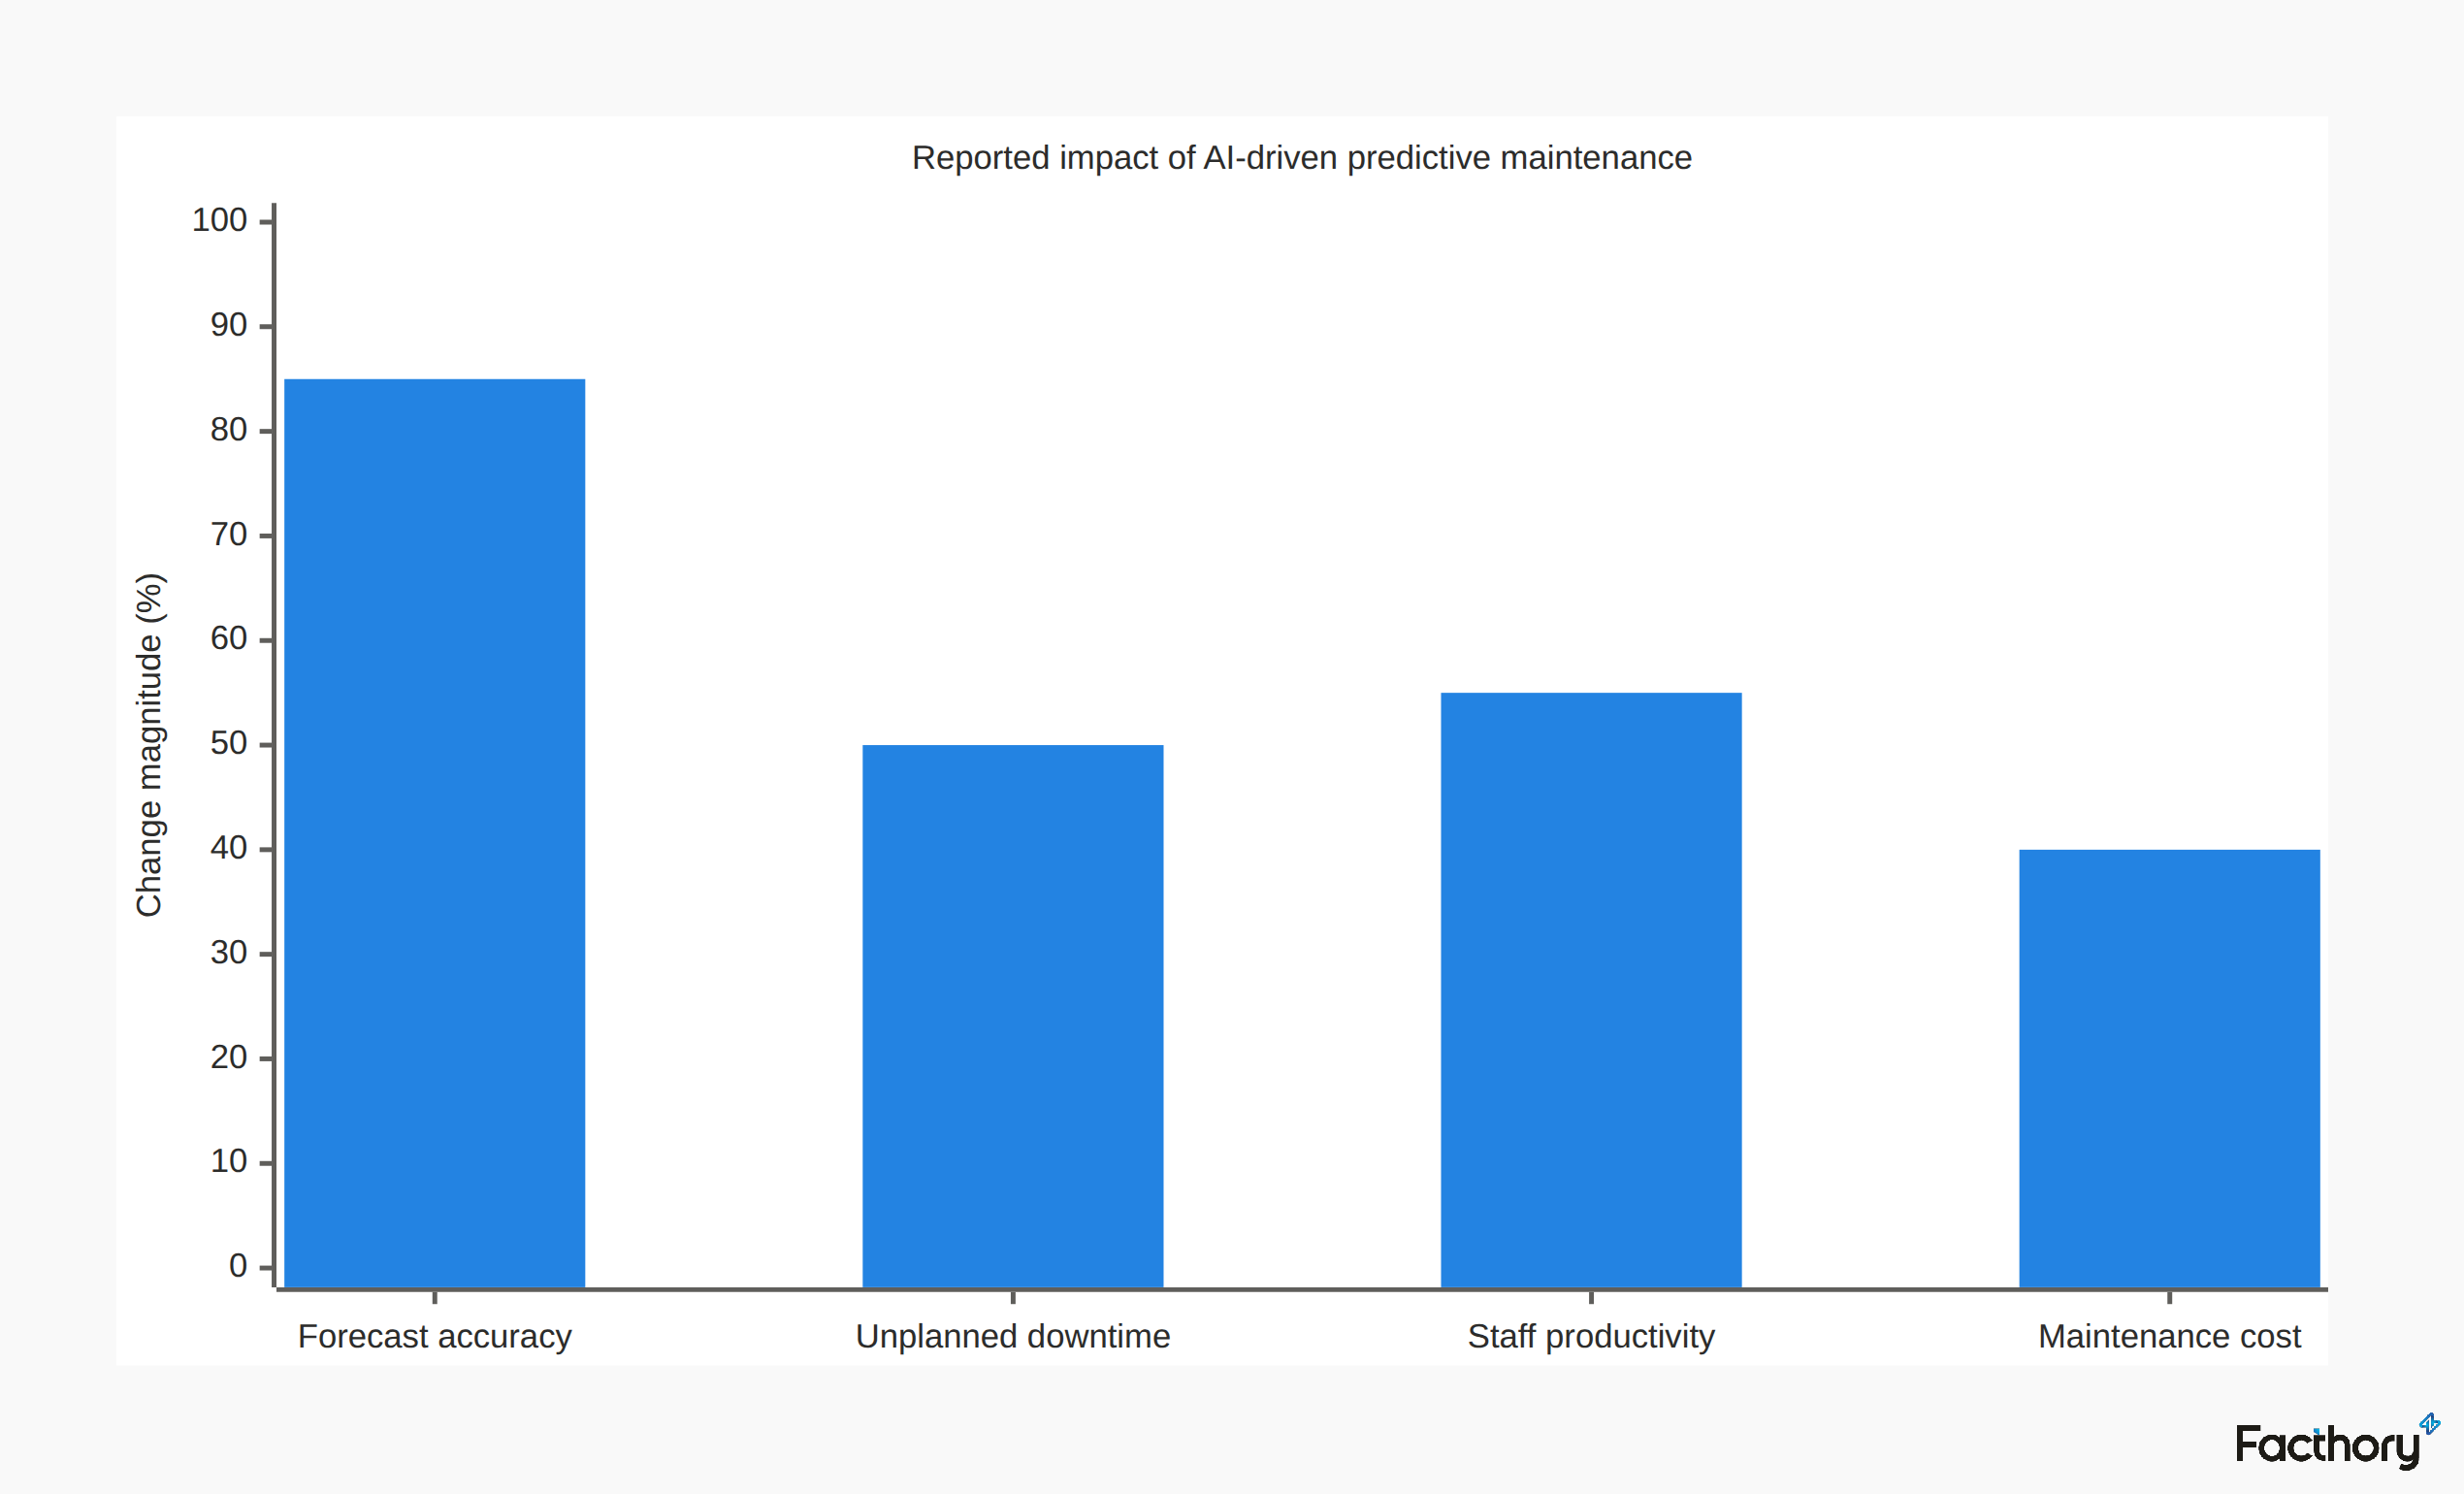
Chart note: positive bars show the magnitude of the reported change. Forecast accuracy and staff productivity increased; unplanned downtime and maintenance costs decreased.
Facthory extends the problem beyond machine health.
A warning is useful. A warning connected to the last three similar defects, the maintenance interventions that preceded them, the engineering change that affected the component, the supplier lot, the relevant procedure, and the people who solved it before is substantially more useful.
And when the investigation is multiplayer, that context does not have to be rediscovered independently by every team.
From root-cause analysis to organizational memory
The end state should not be a better post-mortem document.
When a team validates a root cause, approves a corrective action, and later confirms that the failure did not recur, that result should strengthen the next investigation automatically. The enterprise should become better at solving the second occurrence than the first, and better still at preventing the third.
That is the product direction behind Facthory's quality and reliability intelligence:
-
connect quality, maintenance, engineering, production, and expert evidence
-
let specialist agents investigate different parts of the problem in parallel
-
keep humans inside the same workflow for judgment and approval
-
preserve evidence, hypotheses, decisions, and outcomes as shared operational memory
-
reuse validated learning across assets, lines, products, sites, and future investigations
The key shift is from AI that helps one person answer a question to AI that helps an organization solve a problem together.
For quality, maintenance, and engineering, that is not a cosmetic difference. It is the difference between another copilot and an operational intelligence system.